How Parlant Guarantees Compliance
Many people on social media have been asking recently: "How exactly does Parlant guarantee compliance with conversational LLM agents? How are they able to make that claim?"
This is a crucial question that takes us to the heart of why and how most conversational LLM applications fail in production. The answer lies in first understanding the fundamental types of AI misalignment and how Parlant's architecture systematically addresses each one.
In this article, I'll explain the approach, insights, as well as the core architectural components that make Parlant unique and how they work together to ensure compliance, safety, and reliability in customer-facing AI agents.
Contents:
Two Critical Problems with AI Agents
Before diving into specific types of failures AI agents experience, we should, first of all, understand that there are actually two major challenges to address around failures when building AI agents:
1. Failure Frequency (What Everyone Talks About)
This is the problem measured in percentages—how often your agent makes mistakes. Most discussions about AI reliability focus here: "Our model is 95% accurate" or "We reduced hallucinations by 20%."
2. Failure Severity (What Too Few Talk About)
This is actually the more important problem: how severe are the failures when they do happen?
Here's the key insight: Even if your failure frequency isn't perfect (say, over 10%), as long as your failure severity is bounded so that failures are never truly business-critical, you can actually make your agent deployable in production.
CRITICAL LEVEL
DEPLOYABLE LEVEL
Most teams focus on frequency, but potential severity determines production readiness
In practical terms, this means you can take it to production safely and confidently, then improve your failure frequency through iteration from that solid foundation.
To say it simply: Would you rather have an agent that's 99% accurate but once every 100 conversations may process unauthorized $10,000 refunds, or an agent that's 85% accurate but whose worst mistake is sometimes using slightly awkward phrasing?
Before we dive into the solutions, let's first understand the specific problems that we know occur in customer-facing agents—and here is where, just on the initial "diagnostic" level, it's important that I share some of our actual experience and insights.

The 5 Types of AI Misalignment in Customer-Facing Agents
There are five distinct types of AI misalignment and non-compliance that plague any conversational LLM application:
1. Lack of Focus: Going Off on Tangents
The Problem: The agent responds by going off on tangents and not staying on track to help the customer authoritatively and clearly.
Example:
Customer: "What's the refund policy?"
Expected Response: "We offer a 30-day refund policy for most items. Items must be unused and in original packaging."
Misaligned Agent: "Great question! A refund policy is a set of guidelines that determines whether a customer can return a product and receive a refund. You can consult our refund policy to see if your purchase is eligible for a refund. Additionally, it's important to note that refund policies can vary by product category and may be subject to specific terms and conditions..."
Significance: Customers lose trust in the agent's competence and drop out of the conversation, or escalating to human service, which means you did nothing but lose money on the initial AI interaction.
2. Insufficient Scope: Misinterpreting Context
The Problem: The agent misinterprets the customer's input because it isn't sufficiently grounded in the scope of its job.
Example:
Customer: "Can you help me cancel my subscription?"
Expected Response: "Yes, let me pull up your account details. Can you confirm your email address?"
Misaligned Agent: "I'd be happy to help you cancel! Are you looking to cancel a magazine subscription, streaming service, or maybe a gym membership? I can provide general advice for any of these..."
(When the agent should know it's specifically a customer service agent for a SaaS platform)
Significance: Same issue as above. Lack of competence on the agent's side means lack of trust on the customer's, and they will drop out at that point.
3. Hallucinations: Wrong or Made-Up Information
The Problem: The agent produces wrong or fabricated answers.
Example:
Customer: "What time does your support team work?"
Expected Response: "Our support team is available Monday through Friday, 9 AM to 5 PM Eastern Time. Outside these hours, you can submit a ticket and we'll get back to you the next business day."
Misaligned Agent: "Our support team is available 24/7/365 with live chat, phone, and email support!"
(When in reality, support is only available Monday-Friday, 9 AM-5 PM EST)
Significance: Customers who receive misleading information (on many different levels of severity) lose trust not only in the agent but in the entire brand. This is a critical failure mode that can lead to significant reputational damage.
4. Non-Compliance: Breaching Business Protocol
The Problem: The agent breaches business protocol and causes financial, reputational, or legal damages.
Example:
Customer: "I'm really unhappy with this purchase. Can you give me a full refund and a 50% discount on my next order?"
Expected Response: "I understand your frustration. For refunds, I can process returns within our 30-day policy. For additional compensation, I'd need to connect you with a supervisor who can review your case. How would you like to proceed?"
Misaligned Agent: "Absolutely! I understand your frustration. I've processed a full refund and applied a 50% lifetime discount to your account. Is there anything else I can do to make this right?"
(When the agent has no authority to offer such compensation)
Significance: This gets to the heart of compliance issues. If an agent oversteps its authority, it can lead to significant financial and reputational damage for the company.
5. Unruliness: Ignoring Clear Instructions
The Problem: The agent ignores instructions that were clearly given to it.
Example:
System Instruction: "Always ask for the customer's account number before discussing account details."
Customer: "What's my current balance?"
Expected Response: "Let me help you with that. For security purposes, could you please provide your account number?"
Misaligned Agent: "Your current balance is $2,847.32. Would you like me to help you with anything else regarding your account?"
(Without ever asking for account verification)
Significance: Not following business instructions also leads to issues of multiple severity levels, some of which can be quite critical (e.g., discussing sensitive information without verification).
The Core Issue with Most LLM Apps
I've heard this sentiment countless times from many developers: "When GPT-5 comes out, it'll be a much more powerful model, and it'll solve all the issues we're currently experiencing."
This optimism is understandable—after all, for a short while there we've seen dramatic improvements with new models. The reasoning is that if the model gets bigger, faster, and stronger, then surely it will be able to fix our reliability issues.
Unfortunately, our research has shown us that this approach doesn't hold water. More powerful models don't fundamentally solve the uncertainty problem. Not only are they still prone to statistical issues, but more importantly, we cannot expect them to comprehensively fill in the gaps in the exact way we want them to behave.
On a practical level, the real breakthrough comes from recognizing that we need an architecture that consciously tames uncertainty using human feedback, rather than hoping that raw model capability improvements will solve it. This is what Parlant's all about.
The Curse of Instructions
One of our earliest discoveries, and what has led to Parlant's architecture from day one, is the incredible difficulty of getting LLMs to follow a large set of instructions. Recently, someoneactually wrote a research paper about it, so now we can cite it: The Curse of Instructions.
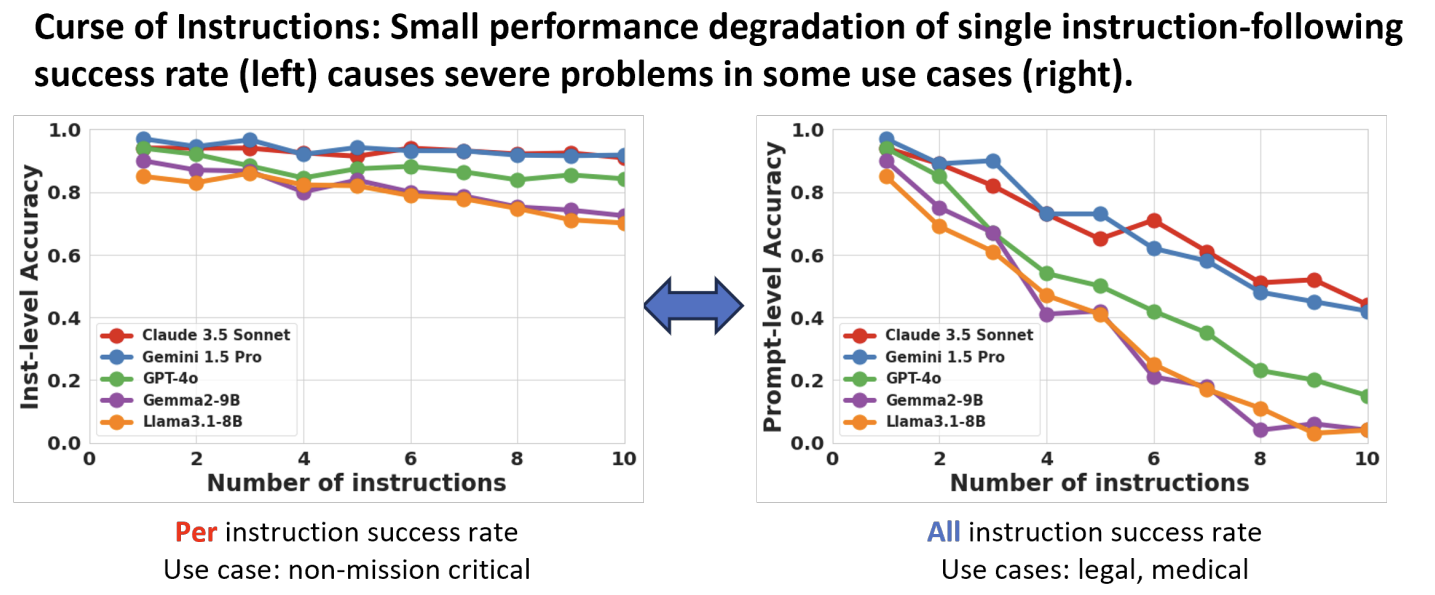
The key insight is that as you add more and more instructions to the model's context, the model's ability to adhere to them degrades quickly and dramatically.
Parlant's guideline matching system (which is perhaps the most important part of its architecture) addresses this problem head-on. It ensures your underlying LLM only sees the few, most-relevant instructions at each point in the agent's processing pipeline by eliminating any noise or irrelevant guidelines from the context.
That keeps the model in the "safe zone" marked in green, where instruction following is highly consistent. And that's the core magic (and, realistically, most of the implementation) of what Parlant does!
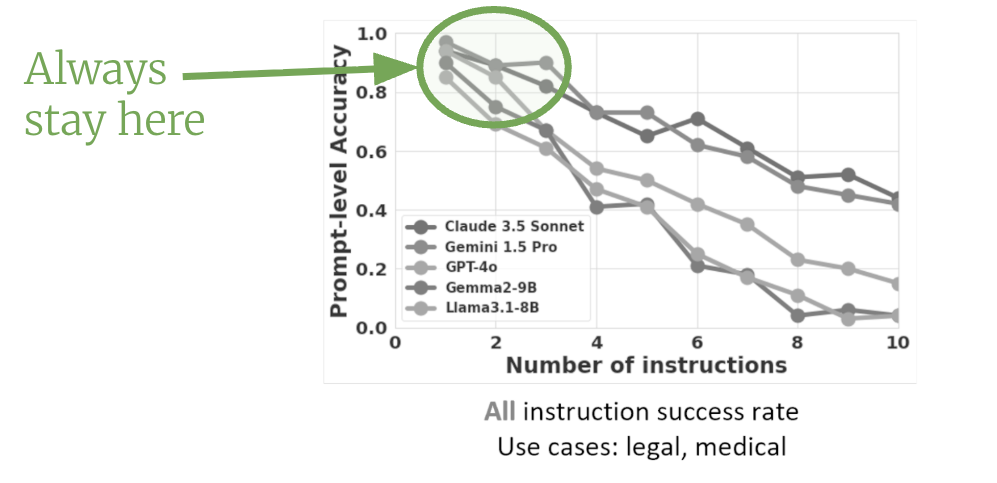
Now, many people, when they see this, assume that guideline matching is simple—like it's doing some vector-based retrieval of relevant guidelines. To that I say: If only. Correct and consistent filtering of contextual instructions is actually extremely complex and nuanced—but that is a topic for another post.
If you're curious, you can look at the guideline_matching directory in the codebase, just to get a sense of how much research and work we constantly put into it, so you don't have to!
Attentive Reasoning Queries (ARQs)
To further ensure consistency and reliability in each of Parlant's components, we also need to touch on our foundational research innovation: Attentive Reasoning Queries (ARQs) (See our research paper at https://arxiv.org/abs/2503.03669), which is how all prompts in Parlant work under the hood.
ARQs leverage two keys properties of LLMs:
- Structured outputs, which allow us to control exactly what type of output comes when, using an ordered schema.
- The Recency Bias of LLMs, which means that the most recent tokens in the prompt have a disproportionately high influence on the output.
By combining these two properties, ARQs allow us to create a structured reasoning process that is highly attentive to the specific information we want the model to consider when making decisions.
Let's look at a simple example of how we match an observational (condition-only) guideline with ARQs. This is the output you'd get. The LLM is asked to complete JSON properties in a controlled, step-by-step manner:
{
  "guideline_id": "fl00LGUyZX",
  "condition": "the customer wants to return an item",
  "condition_application_rationale": "The customer explicitly stated that they need to return a sweater that doesn't fit, indicating a desire to return an item.",
  "condition_applies": true,
}
Notice a few things here:
- We restate the guideline ID and its condition. This is empirically observed to increase accuracy and is hypothesized to help the model "anchor" its reasoning in the right part of its context. Think of this as "explicitly recalling" important information to the top of your mind before making a decision.
- We then ask the model to reason about whether and why the condition applies. This is the reasoning part of ARQs. But now the reasoning is extremely attentive, using the recency bias, to the true condition we need to evaluate.
- Finally, we ask for a prediction. Again, by leveraging the recency bias, the prediction is now highly accurate as it directly follows the guideline and its contextual reasoning.
If you read our paper, you'll see that ARQs achieve roughly the same level of improvement over CoT (Chain-of-Thought) as CoT achieves over no reasoning at all. In other words, ARQs are a game changer in increasing consistency. And the best part is that you can often achieve this improvement with fewer reasoning tokens, since you have so much control over the structure and quality of the reasoning process.
Like I said above, ARQs are used across all of Parlant's components—from guideline matching to tool calling to message composition—ensuring each component performs its job with maximum reliability. In other words, it significantly improves instruction-following alignment.
ARQs dramatically decrease failure frequency by improving instruction-following and preventing hallucinations. While they don't fully solve the failure severity problem, Parlant addresses that with other architectural safeguards, covered further down in this post.
The High-Level Perspective
To look at it from a higher level standpoint, Parlant addresses these misalignment issues through three core architectural components:
Fixing an Agent's Conversational Alignment
Parlant uses two complementary mechanisms to address the misalignment issues identified earlier:
Guidelines tell the agent how to approach specific situations through condition-action pairs:
await agent.create_guideline(
    condition="The customer asks about refunds",
    action="First acknowledge their concern, "
        "then explain our 30-day refund policy"
)
The condition part, unique to Parlant, is crucial to be able to dynamically match and load only the relevant guidelines at each point the agent needs to do some work.
Journeys inform the agent on what your ideal, multi-turn conversational flow is. In other words, how to lead the conversation to where you want it to go, rather than letting the LLM guess it (which it usually does incredibly poorly).
Unlike flowchart-based frameworks, journeys aren't rigid. Parlant agents can work around them to adapt to the customer's needs and interaction patterns, while keeping the bigger picture in mind.
journey = await agent.create_journey(
    title="Handle Refund Request",
    triggers=["The customer wants to return or refund an item"],
    description="Guide customers through our refund process efficiently"
)

first_step = await journey.initial_state.transition_to(
    chat_state="Ask for order ID"
)

second_step = await first_step.target.transition_to(
    tool_state=load_order_details
)

third_step = await second_step.target.transition_to(
    chat_state="Confirm order contents"
)

# etc...
Guidelines and journeys significantly help you reduce and control misalignments of type focus, scope, and compliance. Additionally, both are powered by ARQs, which dramatically improve instruction adherence through structured reasoning.
Like I said, behind the scenes, Parlant dynamically loads only relevant guidelines and journeys for each conversation state, keeping the LLM's "cognitive load" minimal (reducing perplexity) while ensuring consistent behavior across all interactions.
Tool Calling Optimized for Conversational Apps
The main problems with tool calling in LLM applications are threefold:
a. Contextual Overlap: Multiple tools sound plausible for similar situations, creating confusion about which tool to use when.
b. False-Positive Bias: Most foundational LLMs today have a strong tendency toward false positives—they're too eager to call tools even when they shouldn't.
c. Argument Hallucination: Even when the right tool is selected, LLMs often fabricate or guess parameter values instead of asking for missing information.
Parlant solves the first two problems through contextual tool association. Tools are linked to guidelines, meaning they're only evaluated when their associated guideline's condition is matched to the conversation context.
await agent.create_guideline(
    condition="The customer asks about their order status",
    action="Look up their order and provide current status",
    tools=[get_order_status]  # Only evaluated in this context
)
This approach dramatically improves accuracy because tools aren't even considered by the LLM unless the contextual conditions are right. Furthermore, it allows you to use many tools in your agent without confusion—the agent will only consider each tool at the appropriate occasions according to your specifications.
Beyond this foundational improvement, Parlant's tool calling includes several additional innovations for customer-facing applications, solving the most common and critical argument hallucination issues:
Parameter Annotation for Safety:
@p.tool
async def process_refund(
    context: p.ToolContext,
    order_id: Annotated[str, p.ToolParameterOptions(
        source="customer",  # Must come from customer input
    )],
    amount: Annotated[float, p.ToolParameterOptions(
        source="context",   # Can be inferred from order details
    )]
) -> p.ToolResult:
    # Process refund logic here
    pass
Tool Insights for Missing Parameters: Parlant's Tool Insights mechanism allows agents to automatically recognize when parameters are missing and ask for them explicitly:
Agent: "I'd be happy to help you with that refund. Could you please provide your order number so I can look up the details?"
Canned Responses and Strict Mode
Here's where we get to the most gruesome LLM issue of all: potential failure severity. In other words, how can we trust our agents not to royally screw up—not even 1 in a million times? This is actually the most powerful compliance feature Parlant offers for sensitive use cases that truly need it: Canned responses on strict mode:
How it Works:
- The agent drafts a fluid response based on context (taking into account guidelines, tools, and conversation history)
- The engine retrieves and renders relevant pre-approved response templates using in-context field substitutions
- The agent selects and sends the most appropriate canned response
- If no suitable match exists, the agent sends a configurable no-match response
Example Implementation:
# Journey-scoped response candidate
await refund_journey.create_canned_response(
    template="I've processed your refund of {{refund_amount}} "
        "for order {{order_id}}. You'll see it within 5 business days."
)

# Agent-wide response candidate
await agent.create_canned_response(
    template="I'm unable to process that request. "
        "Let me transfer you to a supervisor who can help."
)
Now here's the truly critical safety feature: canned responses that reference fields (like {{refund_amount}}) will never be selected unless those fields are provided by successfully-run tools. This means your agent can never make statements like "Your refund has been processed" unless a tool actually returned a refund_amount field.
This eliminates the risk of the agent claiming business-critical actions were taken when they weren't.
Strict Mode Is NOT Like a Traditional Bot
When they hear about strict mode, many people ask: "If the agent's responses are confined to predefined responses, why not just use a traditional bot?"
This misunderstands what makes Parlant's approach powerful. Here are the key differences:
1. Growing Fluidity Over Time
You can continuously expand your canned response library to approach full fluidity:
# Start with basic responses
await agent.create_canned_response(
    "I just need your order number to get started."
)

await agent.create_canned_response(
    "I can help you with returns. "
    "What's your order number?"
)

# Add more nuanced and fluid variations over time
await agent.create_canned_response(
    "I'd be happy to help you return {{item_name}}. "
    "Could you please provide your order number?"
)
2. Controlled Generative Substitution
Canned responses support confined generative field substitution for context adaptation, while maintaining control over exactly how and where generation is performed:
await agent.create_canned_response(
    "I understand your frustration with {{generative.specific_issue}}. "
    "Would you like me to transfer you to a human agent?"
)
This provides your agent with a controlled measure of fluidity without making the entire response generative, dramatically reducing hallucination risk.
3. The Core Difference: Agentic Behavior vs. Scripted Responses
Here's the most important distinction: canned responses only control the OUTPUT of the agent. The agent's behavior—how it interprets conversations, makes decisions, and acts—remains purely agentic and extremely flexible.
In other words, unlike traditional bots, you're not scripting step-by-step interactions. Instead, you're teaching principles of action:
- "When a customer is upset, acknowledge their feelings first"
- "Always verify account details before discussing sensitive information"
- "Escalate to humans when dealing with complex billing disputes"
The agent applies these principles dynamically, contextually, and intelligently—but expresses the results through an output filter that enforces controlled, compliant language.
And yes, you need to create those canned responses, so it's more work (though much of it can be automated, too).
But at the end of the day, having made this initial (or ongoing) investment in a set of canned responses, you'll be able to release an enterprise-grade AI agent while still being able to sleep at night, knowing it won't cause catastrophic damage to your business.

Experience the Difference
By solving these alignment challenges head-on, Parlant allows you to build deployable agents, while others are still experimenting.
The best way to understand Parlant's approach is to try it yourself. You'll immediately see the difference between:
- Traditional bots: Rigidly scripted, breaking on unexpected input
- Raw LLMs: Unpredictable, non-compliant, risky for production
- Parlant agents: Intelligent, contextual, compliant, and controllable
 Ready to build compliant AI agents?
Parlant is still the only framework that systematically addresses all five types of AI misalignment through architectural design rather than hoping better models will solve the problems. Try it today and see why we say compliance isn't just a promise—it's a guarantee.